A former English Professor recently emailed me telling me of a student he caught plagiarizing. His answer on a Shakespeare quiz was word for word copied from somewhere else. When confronted, the student's defense was that it was a coincidence. He adds:
This got me to thinking about the letters of the alphabet, words in the language, the context of the sentences (which is a variable we could not manage, though the quiz certainly restricts the word choices to those related to its questions) . . . it seems big, maybe too big, but if you happen to know how we could use Mathematics to reveal to the cheater that he must have cheated, that would be pretty cool.
My edited and reformatted response:
There are a lot of problems with analyzing something like this. Rather than try to solve it and post a nice (and probably very wrong) answer, I'll take you down the rabbit hole with me. I'm going to use my standard strategy of making bad guesses then refining those guesses. Like rough drafting.
The first thing I want is an upper bound on the total number of possible sentences. I'm not sure what the typical sentence length is (that's a problem for another day), so I'll use one of my professor's sentences as my standard: "I'm heartened to know that you are just as bad at maintaining relationships as I am." This has 84 characters and I'm going to assume this is typical. Assuming the standard sentence in composed of 31 characters [footnote 1], there are 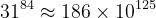 that's 186000000000000000000000000000000000000000000000000000000000000000000000000000000000000000000000000000000000000000000000000000 different possible strings of length 84 (this is way more than the number of atoms in our universe). These "sentences" would look like:
- "lifr ,srpx'p,sxtvamhw ott'au, xre'idm'ansbicbrshpn,khi,z' .qznkwggp w'lrufpxfsftk?mb"
- " .rk'oeblct?bf?ibz?tj,vyelqg'ixulg'k.mdwanxeskybhhewhqscyms aukmtxknyjl ?mzgzmgpkqja"
- "most of the sentences will be meaningless gibberish, but some will be like this one."
- "aaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaa"
- "I'm heartened to know that you are just as bad at maintaining relationships as I am."
This, of course, doesn't come close to answering the question because we can discount sentences like "lifr ,srpx'p,sxtvamhw ott'au, xre'idm'ansbicbrshpn,khi,z' .qznkwggp w'lrufpxfsftk?mb" For more on this, consult Jorge Luis Borges.
So we need to limit our possible sentences to just possible combinations of words, not combinations of characters. There are about a quarter of a million words in the English language. Assuming the average sentence is 16 words long (number of words in "I'm heartened to know that you are just as bad at maintaining relationships as I am."), then there are 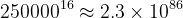 or 230000000000000000000000000000000000000000000000000000000000000000000000000000000000000 possible sentences. This is way smaller, but still more than the number of atoms in the universe. This includes sentences like [footnote 2]:
- "London the fuel previously Like based, different Torphin population fascinated to cards objects was objects bottles,"
- "a predominantly 1992 Trustco of firm's so different banking main where people and being manner hill "
- "cat cat cat cat cat cat cat cat cat cat cat cat cat cat cat cat"
- "Just like what happened before, most of the sentences will be completely nonsensical and totally meaningless."
- "I'm heartened to know that you are just as bad at maintaining relationships as I am."
So this is still problematic. Just like before, the number of sentences here isn't a good approximation of the number of possible sentences you would expect as the answer to a test question because the vast majority of them are total nonsense. This number needs to be reduced further still, but here is where the problem arises. How do we go about counting the total number of meaningful sentences? It'd be hard, but not impossible. Given enough time and computer power, I'd do something like this:
- Write a program to randomly generate sentences. I've kinda already done this (see footnote 2 if you haven't already).
- Write a program that checks the meaningfulness of a sentence. This seems hard, but it doesn't have to be that good. I'm thinking something like Microsoft's grammar checker. For a more expensive, but more accurate alternative, see footnote 3.
- Take the output from step 1 and run it through the program in step 2. This will tell us what percentage of possible sentences are meaningful sentences.
- Once we have an idea of what percentage of possible sentences are meaningful we can find the total number of meaningful sentences.
This is a statistical approach. We won't be generating every possible sentence, just a bunch of them.
The things is, this still doesn't do the trick. The set of all meaningful sentences is still too big. This set includes sentences like [footnote 4]:
- Before 1945 the area was part of Germany.
- Her power can cause torrential rain and flooding.
- Upon Bourchier's death Elizabeth remarried to the 2nd Earl Rivers, brother of Elizabeth Woodville, wife of King Edward IV.
- LOF ordered new tanker ships, the first of which were the London Pride (I) and London Enterprise (I) completed by Furness Shipbuilding at Stockton-on-Tees in 1950.
- Rai started his career as a secondary school teacher.
I don't think any of these could realistically be considered answers on a quiz about Shakespeare. So once again we need to filter this set down to a smaller set: the set of all sentences about Shakespeare. But even this set might be too big ("Shakespeare was the first dinosaur to land on Mars" is a sentence about Shakespeare, but probably wouldn't show up as an answer on a quiz. Which is too bad; I think I'd enjoy classic literature more if this was a possibility.)
So in descending order of sizes, the sets we’ve considered are:
- The set of all 84 character strings
- The set of all 16 word sentences
- The set of all meaningful sentences
- The set of all sentences about Shakespeare
- The set of all sentences that could realistically be considered answers on a Shakespeare quiz.
Set (5) is still an absurdly huge set, but I have no Idea how to go about determining how big it is. Suffice to say that it's big enough that you couldn't coincidentally duplicate a sentence.
One quick side note: This email is concerned with upper bounds. I've made no effort to build a lower bound, and I don't really have any good ideas about how I might do that. You might count all the answers you've gotten on previous quizzes. This will give you a very, very low lower bound. Too low to be of any real use.
-Nick
FOOTNOTES
[1] The 31 characters I'm using are abcdefghijklmnopqrstuvwxyz ,.'? Not included in this list are capitals, quotation marks, and exclamation marks. Let me justify this:
- I think it's fine to assume our sentence can be thrown through an automatic capitalizing machine. Once this is done, a sentence like "he is not as smart as i am." will be converted to "He is not as smart as I am." This process is straightforward, and will greatly reduce our upper bound by not distinguishing between strings like: "the cat," "The Cat," and "ThE cAt."
- We can consider a quote as the same as a double apostrophe. Grammatically this may be heinous, but typographically, it really doesn't make a difference.
- Exclamation marks can go to hell.
[2] Rather than try to come up with randomly worded sentences, I wrote a program that pulls random words off of Wikipedia then rearranges them into a truly random sentence. Was this overkill? Yes. Did this take way more time than necessary? Yes. Did this in any way help make my point? No. Similarly, the random character sentences from before were also computer generated, not the product of keyboard smashing.
[3] The hottest thing right now in data analysis is crowd-sourcing.
- Randall Munroe, author of XKCD, one of my favorite web comics, had his readers (including me) participate in a color survey. Participants were asked to name randomly generated colors. His description of the results is awesome.
- Amazon has a program called Amazon Turks that pays people a few pennies to do menial tasks like classifying pictures.
- The Guardian had its readers analyze a ton of MP receipts.
- You can even trick your crowd into thinking what they're doing is fun. This is an article about a biology problem solved with gaming. This blog describes and links to a game that has players design computer chips.
[4] Yes, these too were randomly generated by a program I wrote. This program goes to a random Wikipedia article, and grabs a random sentence. I wrote this program a few months ago, and I was quite certain at the time that I'd never have any use for it. Turns out I was wrong.